论文成果 / Publications
2024
ContextCam: Bridging Context Awareness with Creative Human-AI Image Co-Creation
Abstract
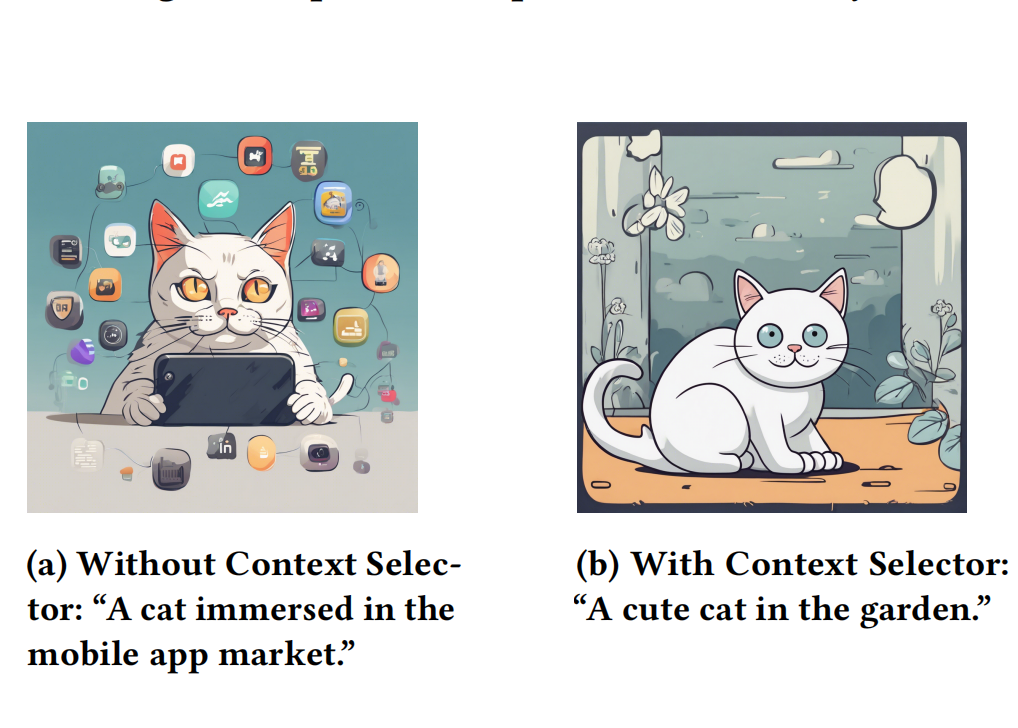
The rapid advancement of AI-generated content (AIGC) promises to transform various aspects of human life significantly. This work particularly focuses on the potential of AIGC to revolutionize image creation, such as photography and self-expression. We introduce ContextCam, a novel human-AI image co-creation system that integrates context awareness with mainstream AIGC technologies like Stable Diffusion. ContextCam provides user’s image creation
process with inspiration by extracting relevant contextual data, and leverages Large Language Model-based (LLM) multi-agents to co-create images with the user. A study with 16 participants and 136 scenarios revealed that ContextCam was well-received, showcasing personalized and diverse outputs as well as interesting user behavior patterns. Participants provided positive feedback on their engagement and enjoyment when using ContextCam, and acknowledged its ability to inspire creativity.
ContextMate: a context‑aware smart agent for efficient data analysis
Abstract
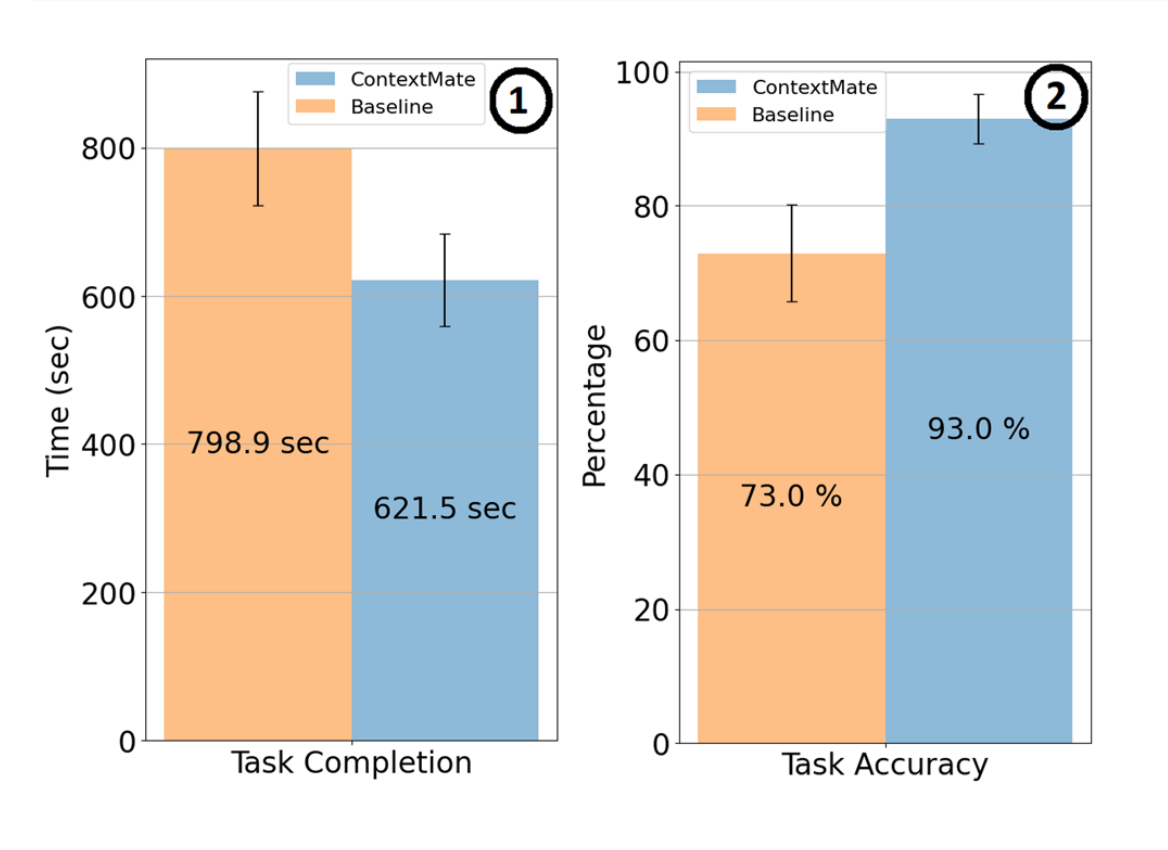
Pre-trained large language models (LLMs) have demonstrated extraordinary adaptability across varied tasks, notably in data analysis when supplemented with relevant contextual cues. However, supplying this context without compromising data privacy can prove complicated and time-consuming, occasionally impeding the model’s output quality. To address this, we devised a novel system adept at discerning context from the multifaceted desktop environments commonplace amongst office workers. Our approach prioritizes real-time interaction with applications, according precedence to those recently engaged
with and have sustained prolonged user interaction. Observing this landscape, the system identifies the dominant data analysis tools based on user engagement and intelligently aligns concise user queries with the data’s inherent structure to determine the most appropriate tool. This meticulously sourced context, when combined with optimally chosen prefabricated prompts, empowers LLMs to generate code that mirrors user intentions. An evaluation with 18 participants, each using three popular data analysis tools in real-world office and R &D scenarios, benchmarked our approach against a conventional baseline. The results showcased an impressive 93.0% success rate of our system across seven distinct data-focused tasks. In conclusion,
our method significantly improves user accessibility, satisfaction, and comprehension in data analytics.
2023

Game Interactive Learning: A New Paradigm towards Intelligent Decision-Making
Abstract
Decision-making plays an essential role in various real-world systems like automatic driving, traffic dispatching, information system management, and emergency command and control. Recent breakthroughs in computer game scenarios using deep reinforcement learning for intelligent decision-making have paved decision-making intelligence as a burgeoning research direction. In complex practical systems, however, factors like coupled distracting features, long-term interact links, and adversarial environments and opponents, make decision-making in practical applications challenging in modeling, computing, and explaining.This work proposes game interactive learning, a novel paradigm as a new approach towards intelligent decision-making in complex and adversarial environments. This novel paradigm highlights the function and role of a human in the process of intelligent decision-making in complex systems. It formalizes a new leaming paradigm for exchanging information and knowledgebetween humans and the machine system. The proposed paradigm first inhenits methods in game theory to model the agents andtheir preferences in the complex decision-making process. It then optimizes the learning objectives from equilibnium analysis usingreformed machine learning algorithms to compute and pursue promising decision results for practice. Human interactions areinvolved when the learning process needs guidance from additional knowledge and instructions, or the human wants to understandthe leaming machine better. We perform preliminary expenimental verification of the proposed paradigm on two challengingdecision-making tasks in tactical-level War-game scenarios. Experimental results demonstrate the effectiveness of the proposed learning paradigm.
Docent: Digital Operation-Centric Elicitation of Novice-friendly Tutorials
Abstract
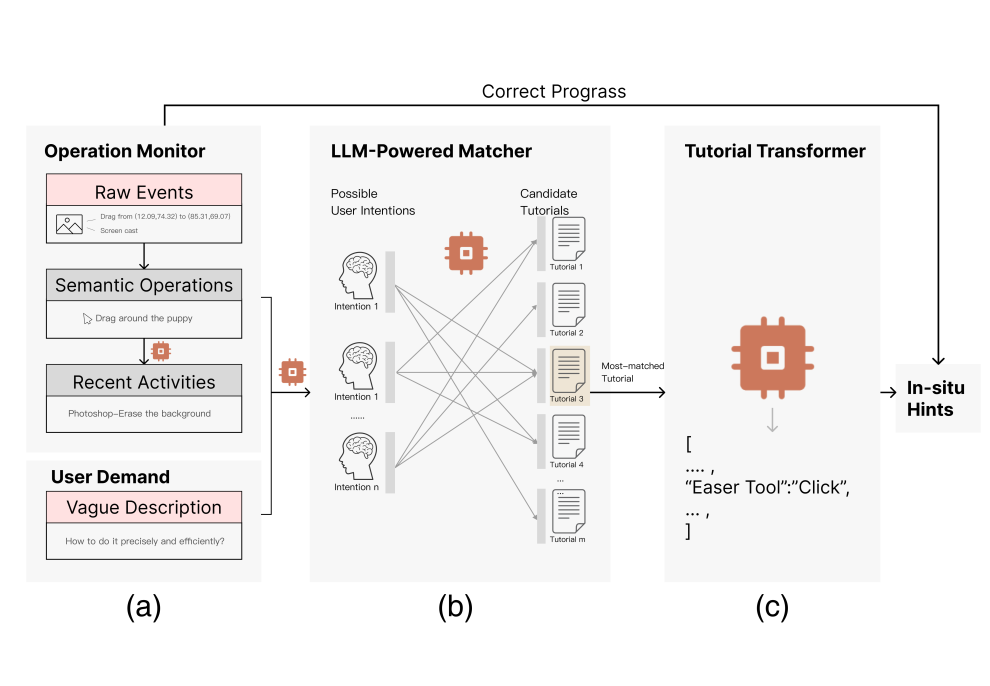
Nowadays, novice users often turn to digital tutorials for guidance in software. However, searching and utilizing the tutorial remains a challenge due to the request for proper problem articulation, extensive searches and mind-intensive follow-through. We introduce "Docent", a system designed to bridge this knowledge-seeking gap.Powered by Large Language Models (LLMs), Docent takes vague user input and recent digital operation contexts to reason, seek,
and present the most relevant tutorials in-situ. We assume that Docent smooths the user experience and facilitates learning of the software.
Lightron: A Wearable Sensor System that Provides Light Feedback to Improve Punching Accuracy for Boxing Novices
Abstract
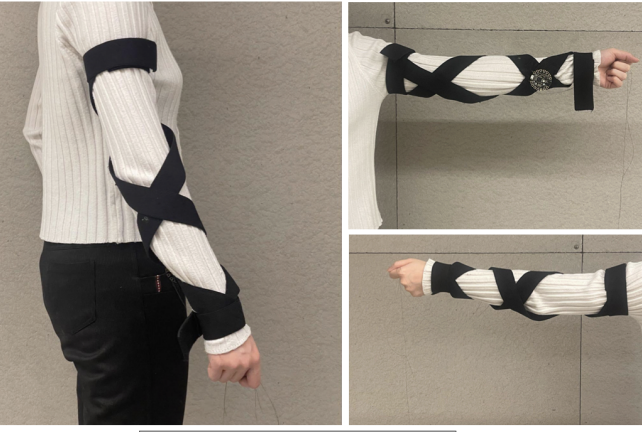
This work presents ‘Lightron’, a wearable sensor system designed for boxing training assistance, improving punching accuracy for novices. This system combines accelerometers, stretch sensors, and flex sensors to detect the user’s movements, providing LED light feedback to the user. This adjustable design ensures a tight fit of the device to the body, allowing the sensor to collect accurate arm movement data without impeding training movements. A simple neural network is used to enable real-time motion detection and analysis, which can run on low-cost embedded devices. Contrary to merely using accelerometers on the wrist, Lightron collects motion data from the elbow and shoulder, enhancing the precision of punch accuracy assessment. Primary user studies conducted among boxing amateurs have shown that using Lightron in boxing training increases the performance of amateur players both in single and periodic training sessions, demonstrating its potential utility in the sports training domain.
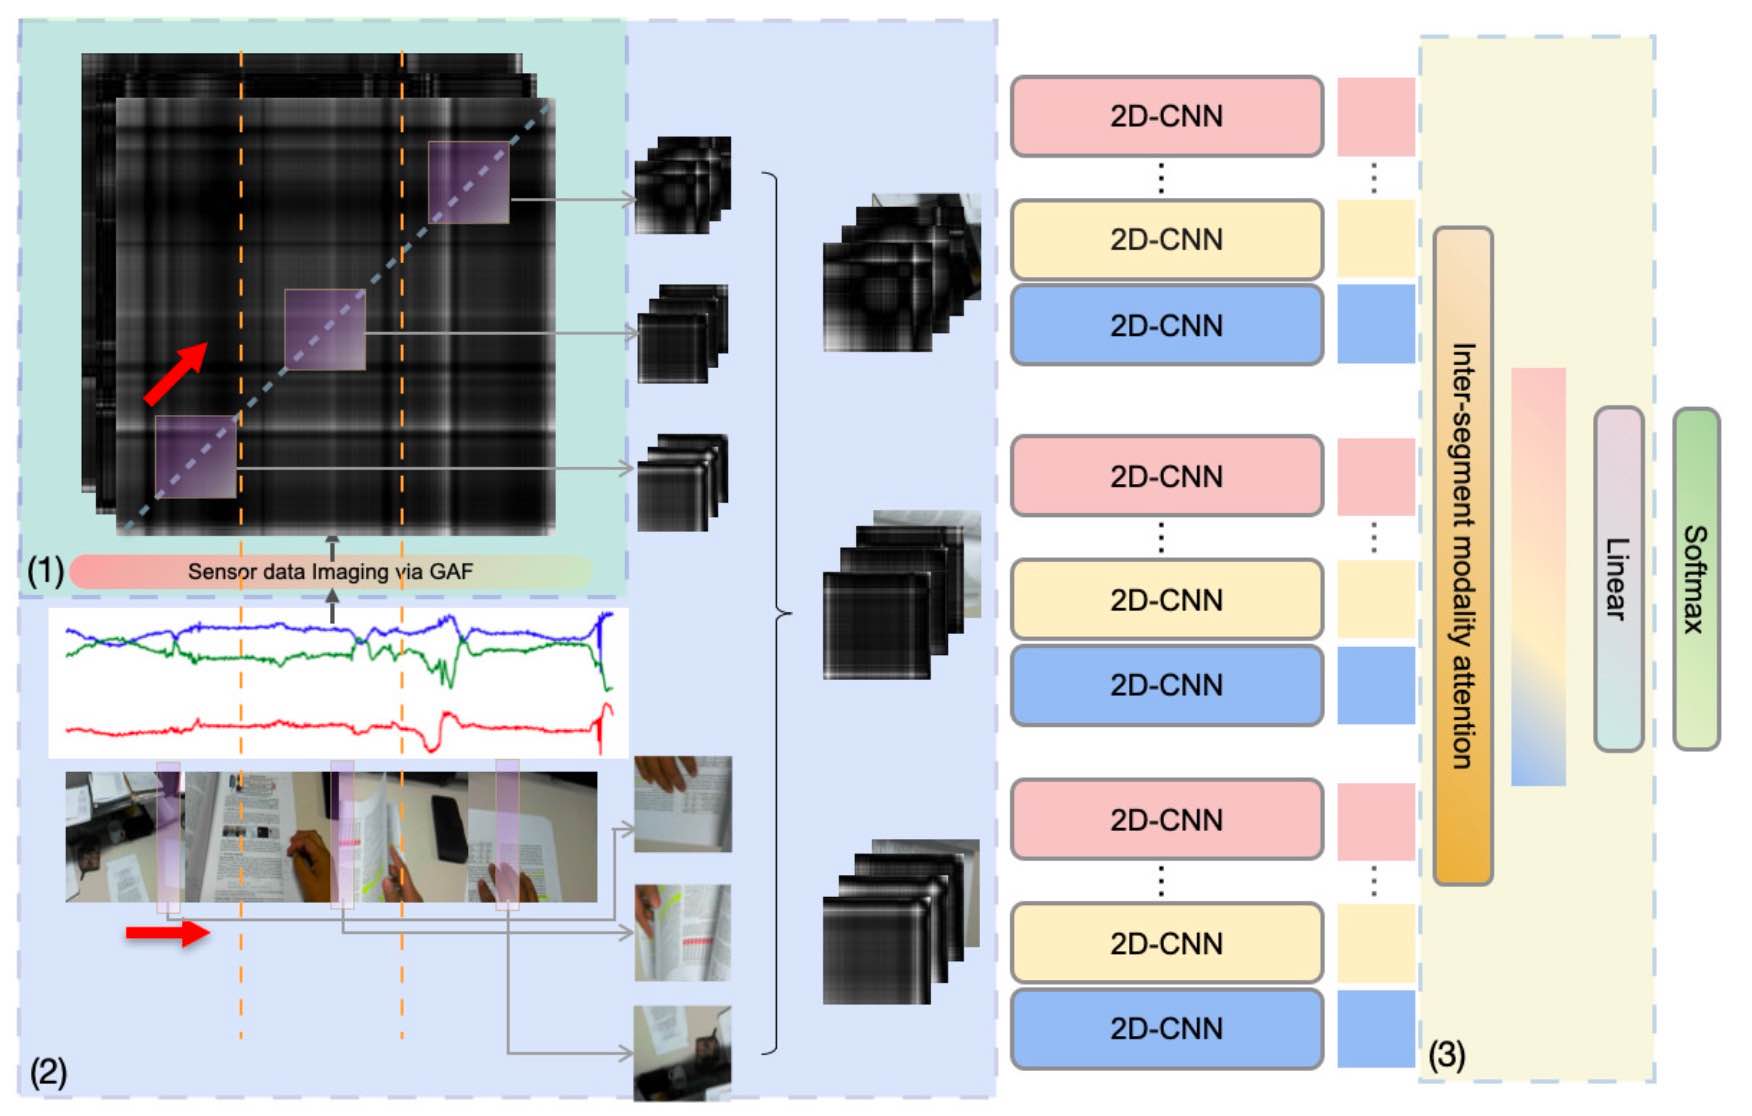
MMTSA: Multi-Modal Temporal Segment Attention Network for Efficient Human Activity Recognition
Abstract
Multimodal sensors provide complementary information to develop accurate machine-learning methods for human activity recognition (HAR), but introduce significantly higher computational load, which reduces efficiency. This paper proposes an efficient multimodal neural architecture for HAR using an RGB camera and inertial measurement units (IMUs) called Multimodal Temporal Segment Attention Network (MMTSA). MMTSA first transforms IMU sensor data into a temporal and structure-preserving gray-scale image using the Gramian Angular Field (GAF), representing the inherent properties of human activities. MMTSA then applies a multimodal sparse sampling method to reduce data redundancy. Lastly, MMTSA adopts an inter-segment attention module for efficient multimodal fusion. Using three well-established public datasets, we evaluated MMTSA's effectiveness and efficiency in HAR. Results show that our method achieves superior performance improvements (11.13% of cross-subject F1-score on the MMAct dataset) than the previous state-of-the-art (SOTA) methods. The ablation study and analysis suggest that MMTSA's effectiveness in fusing multimodal data for accurate HAR. The efficiency evaluation on an edge device showed that MMTSA achieved significantly better accuracy, lower computational load, and lower inference latency than SOTA methods.
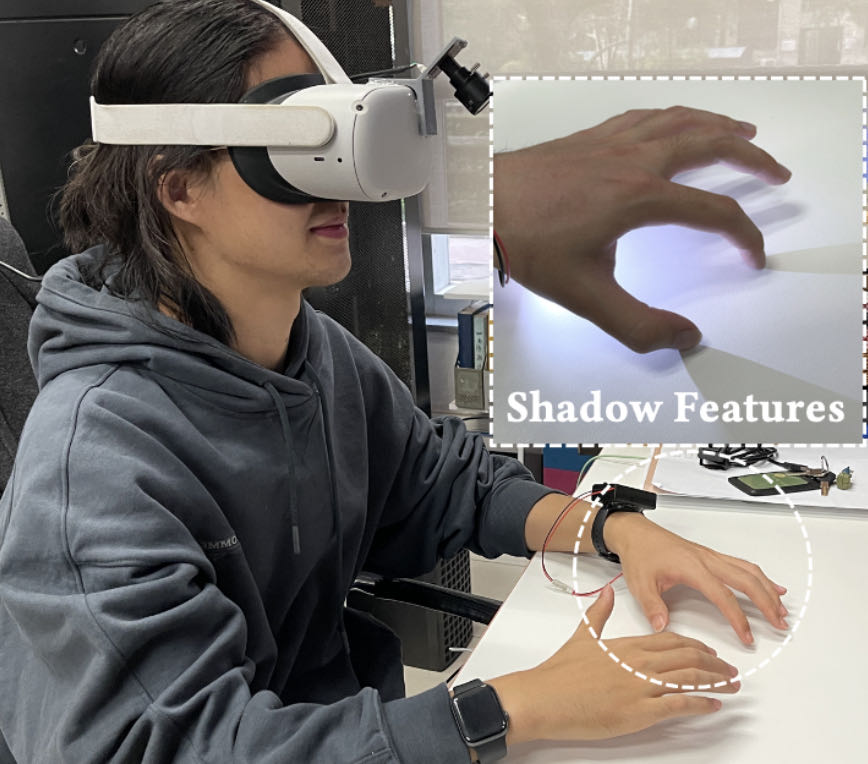
ShadowTouch: Enabling Free-Form Touch-Based Hand-to-Surface Interaction with Wrist-Mounted Illuminant by Shadow Projection
Abstract
We present ShadowTouch, a novel sensing method to recognize the subtle hand-to-surface touch state for independent fingers based on optical auxiliary. ShadowTouch mounts a forward-facing light source on the user’s wrist to construct shadows on the surface in front of the fingers when the corresponding fingers are close to the surface. With such an optical design, the subtle vertical movements of near-surface fingers are magnified and turned to shadow features cast on the surface, which are recognizable for computer vision algorithms. To efficiently recognize the touch state of each finger, we devised a two-stage CNN-based algorithm that first extracted all the fingertip regions from each frame and then classified the touch state of each region from the cropped consecutive frames. Evaluations showed our touch state detection algorithm achieved a recognition accuracy of 99.1% and an F-1 score of 96.8% in the leave-one-out cross-user evaluation setting. We further outlined the hand-to-surface interaction space enabled by ShadowTouch’s sensing capability from the aspects of touch-based interaction, stroke-based interaction, and out-of-surface information and developed four application prototypes to showcase ShadowTouch’s interaction potential. The usability evaluation study showed the advantages of ShadowTouch over threshold-based techniques in aspects of lower mental demand, lower effort, lower frustration, more willing to use, easier to use, better integrity, and higher confidence.
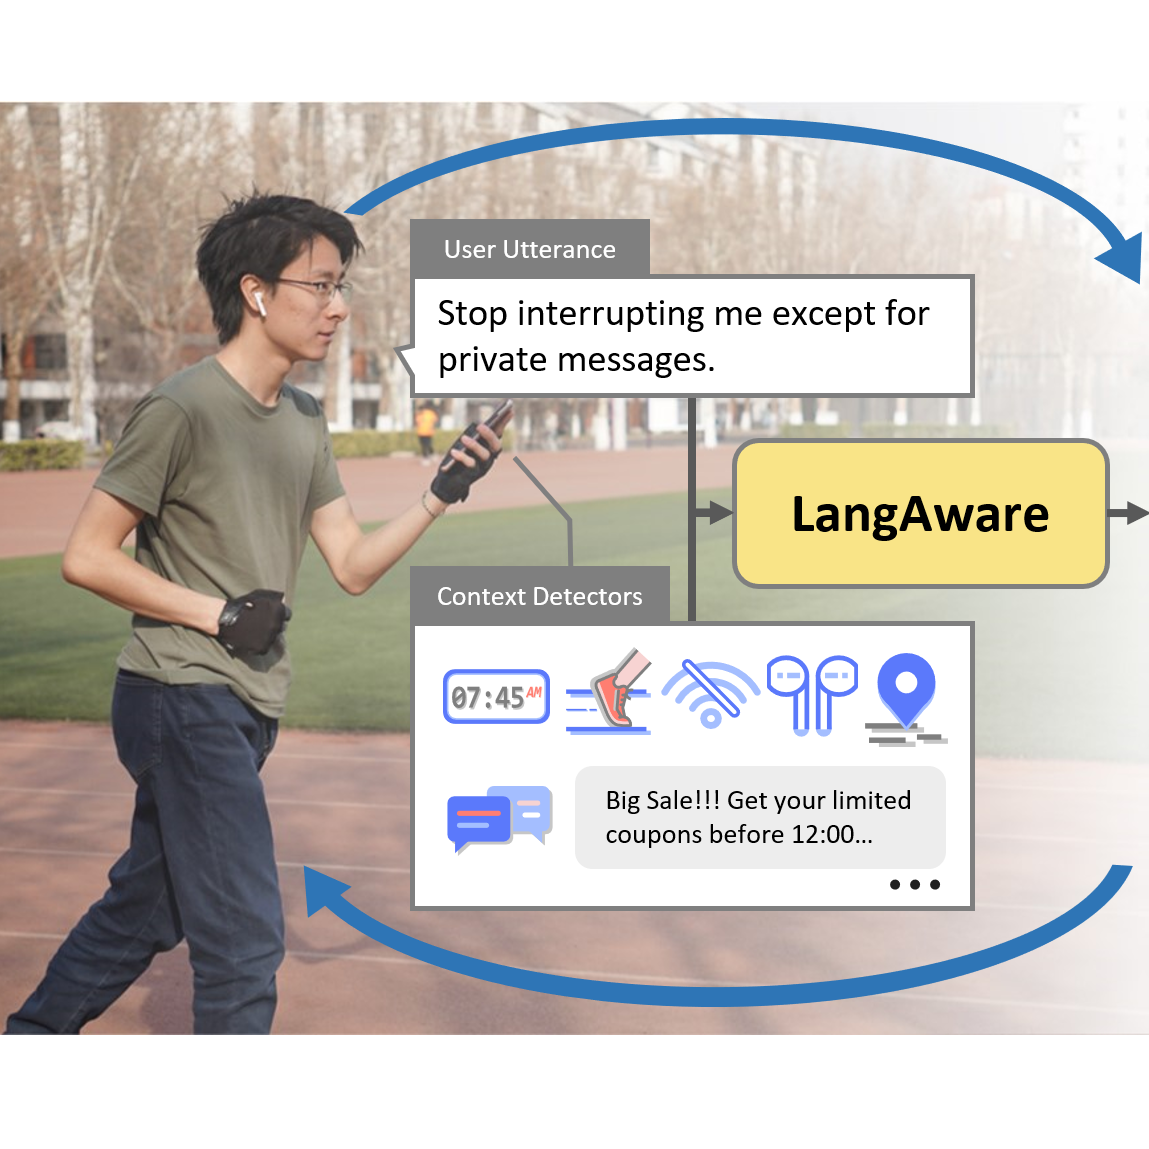
From Gap to Synergy: Enhancing Contextual Understanding through Human-Machine Collaboration in Personalized Systems
Abstract
This paper presents LangAware, a collaborative approach for constructing personalized context for context-aware applications. The need for personalization arises due to significant variations in context between individuals based on scenarios, devices, and preferences. However, there is often a notable gap between humans and machines in the understanding of how contexts are constructed, as observed in trigger-action programming studies such as IFTTT. LangAware enables end-users to participate in establishing contextual rules in-situ using natural language. The system leverages large language models (LLMs) to semantically connect low-level sensor detectors to high-level contexts and provide understandable natural language feedback for effective user involvement. We conducted a user study with 16 participants in real-life settings, which revealed an average success rate of 87.50% for defining contextual rules in a variety of 12 campus scenarios, typically accomplished within just two modifications. Furthermore, users reported a better understanding of the machine’s capabilities by interacting with LangAware.
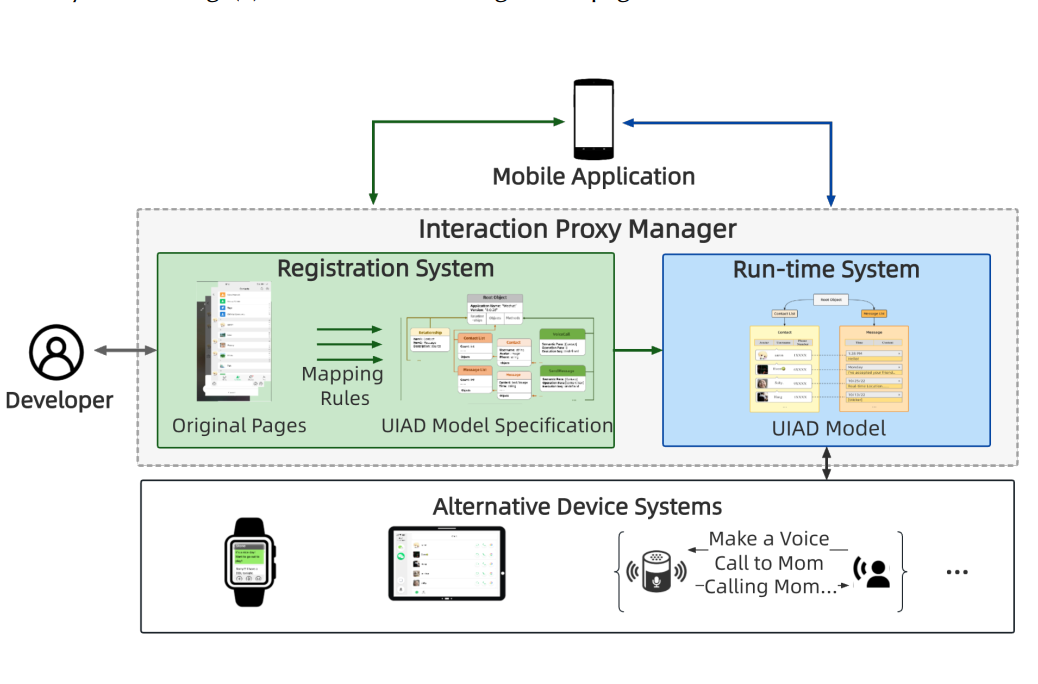
Interaction Proxy Manager: Semantic Model Generation and Run-time Support for Reconstructing Ubiquitous User Interfaces of Mobile Services
Abstract
Emerging terminals, such as smartwatches, true wireless earphones, in-vehicle computers, etc., are complementing our portals to ubiquitous information services. However, the current ecology of information services, encapsulated into millions of mobile apps, is largely restricted to smartphones; accommodating them to new devices requires tremendous and almost unbearable engineering efforts. Interaction Proxy, firstly proposed as an accessible technique, is a potential solution to mitigate this problem. Rather than re-building an entire application, Interaction Proxy constructs an alternative user interface that intercepts and translates interaction events and states between users and the original app’s interface. However, in such a system, one key challenge is how to robustly and efficiently “communicate” with the original interface given the instability and dynamicity of mobile apps (e.g., dynamic application status and unstable layout). To handle this, we first define UI-Independent Application Description (UIAD), a reverse-engineered semantic model of mobile services, and then propose Interaction Proxy Manager (IPManager), which is responsible for synchronizing and managing the original apps’ interface, and providing a concise programming interface that exposes information and method entries of the concerned mobile services. In this way, developers can build alternative interfaces without dealing with the complexity of communicating with the original app’s interfaces. In this paper, we elaborate the design and implementation of our IPManager, and demonstrate its effectiveness by developing three typical proxies, mobile-smartwatch, mobile-vehicle and mobile-voice. We conclude by discussing the value of our approach to promote ubiquitous computing, as well as its limitations.